
Any identity. Native 2K. Unlimited duration.
Generate talking videos from a single photo, optionally with a short recording as an identity reference, across diverse identities and visual styles, at up to 2K and with no fixed duration limit.
Gestures on cue.
Write the action next to the words. Avatar 6 performs it right on cue, in the person's own style.
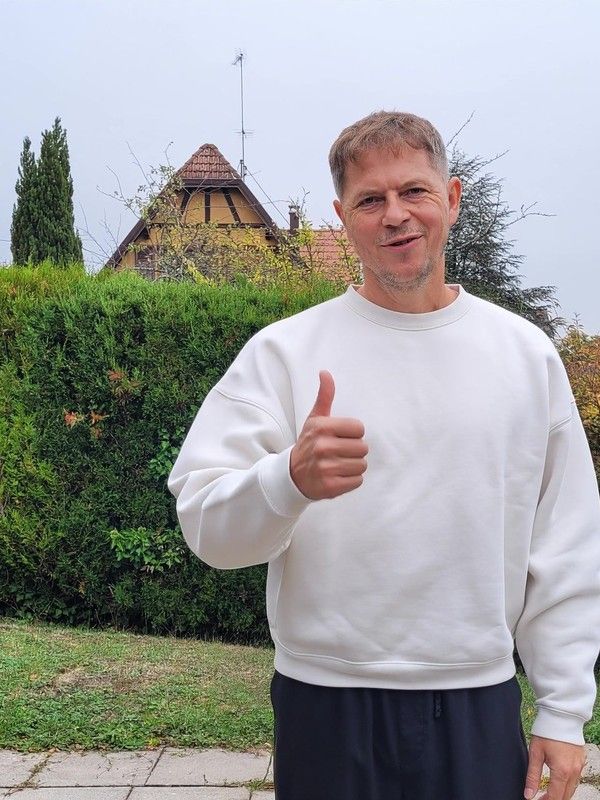
thumbs up
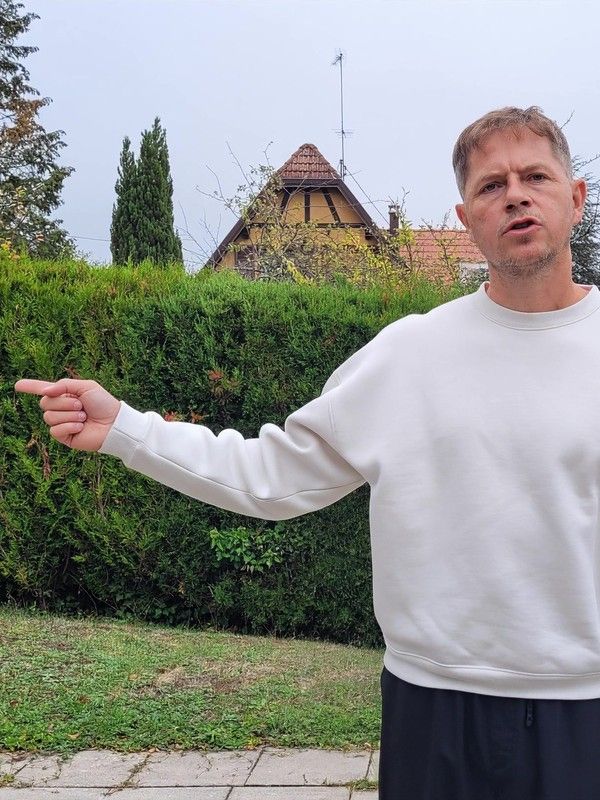
point to the side
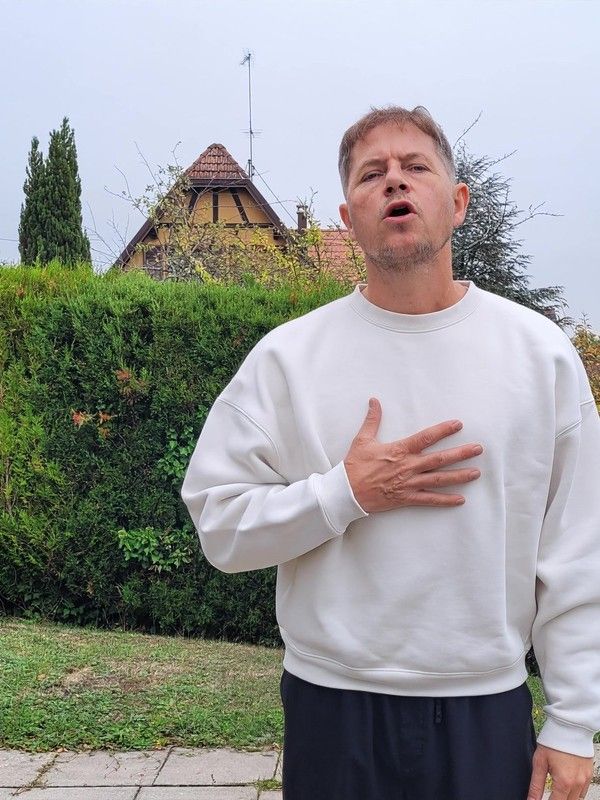
hand on heart
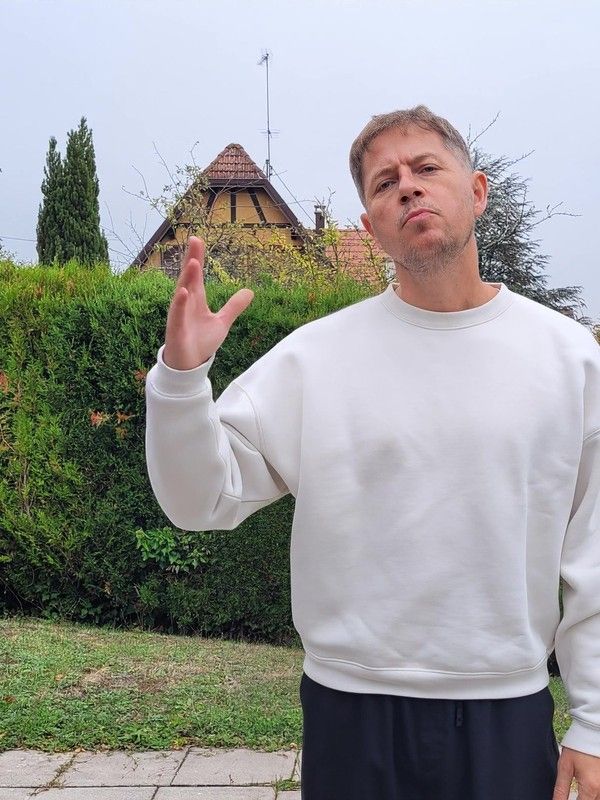
wave
Prompt Friendly pharmacist. On ‘Hello', give a thumbs up. On ‘the counter on the left', point to the side with your index finger. On ‘always happy to chat', place your right hand on your heart. On ‘Take a seat', open both arms wide. On ‘some water', wave your right hand.
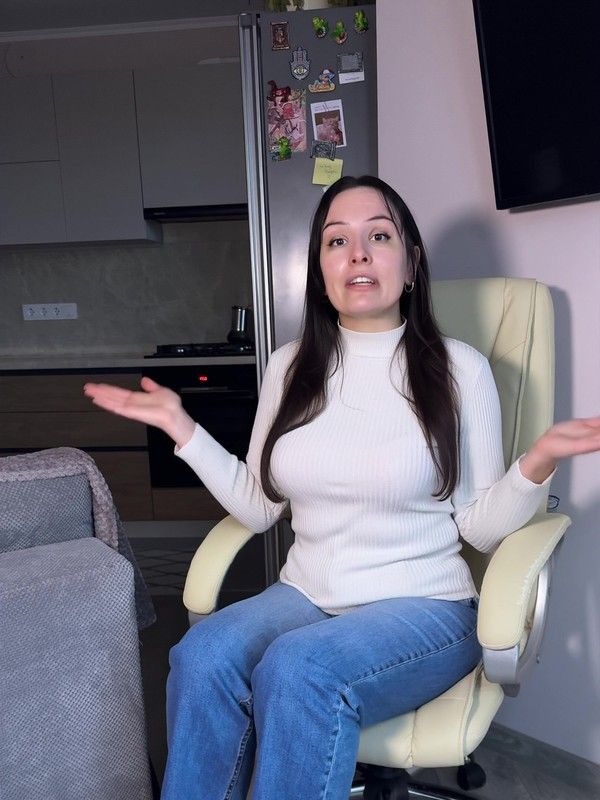
arms open, palms up
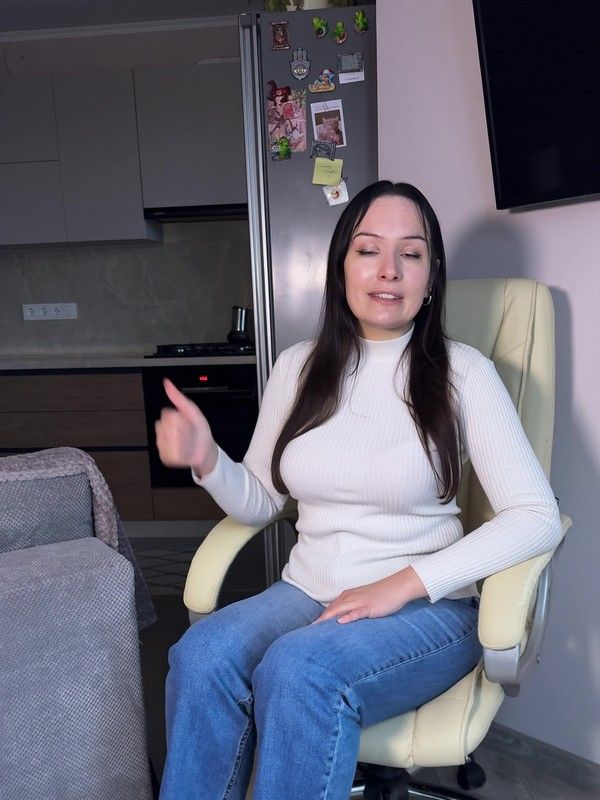
thumbs up
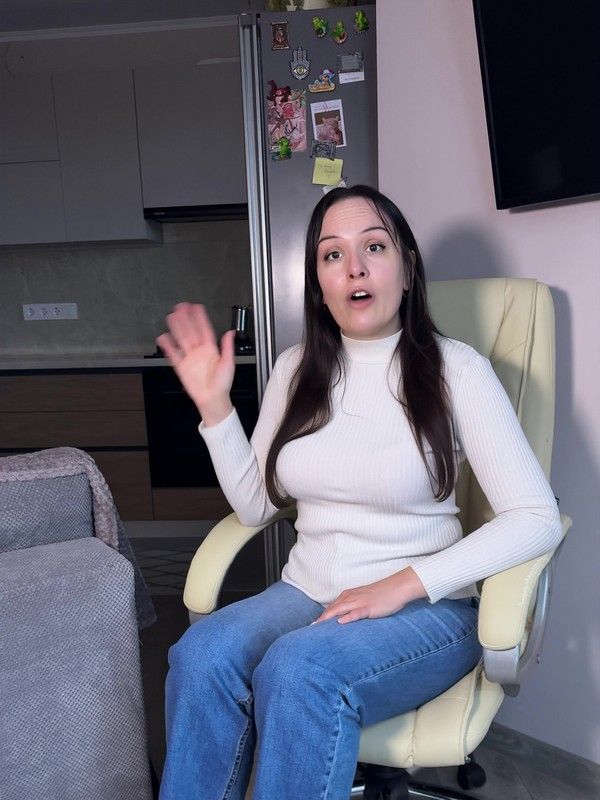
wave
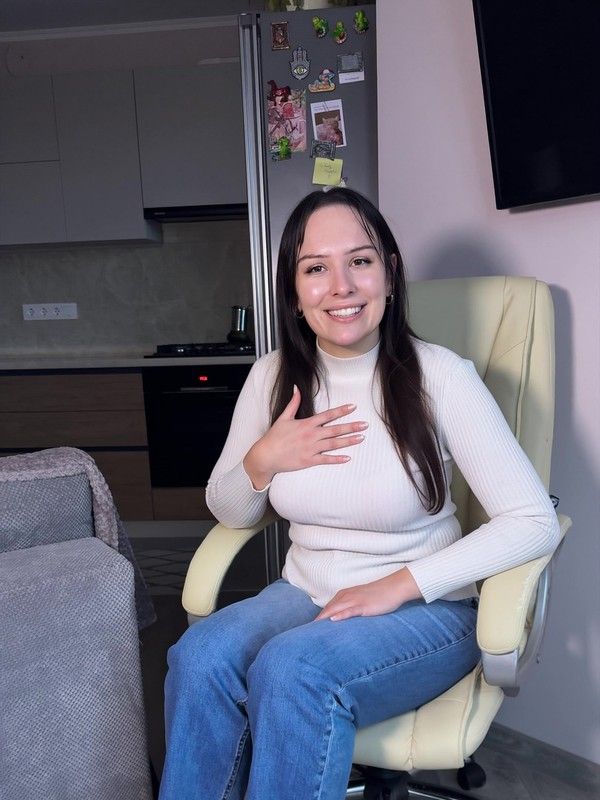
hand on heart
Prompt Warm clinic host. On ‘Welcome', open both arms wide, palms up. On ‘grandparents', give a thumbs up. On ‘front desk', wave your right hand. On ‘Thanks for trusting us', place your right hand on your heart.
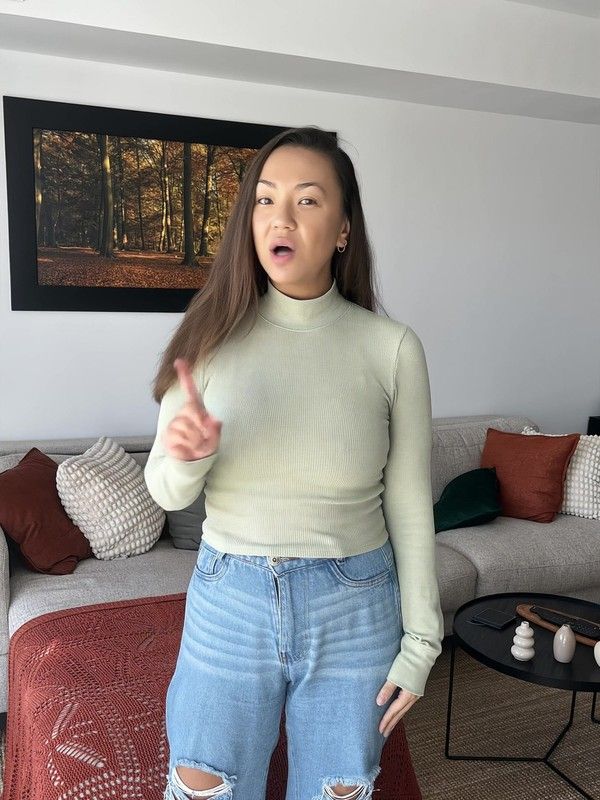
wag index finger
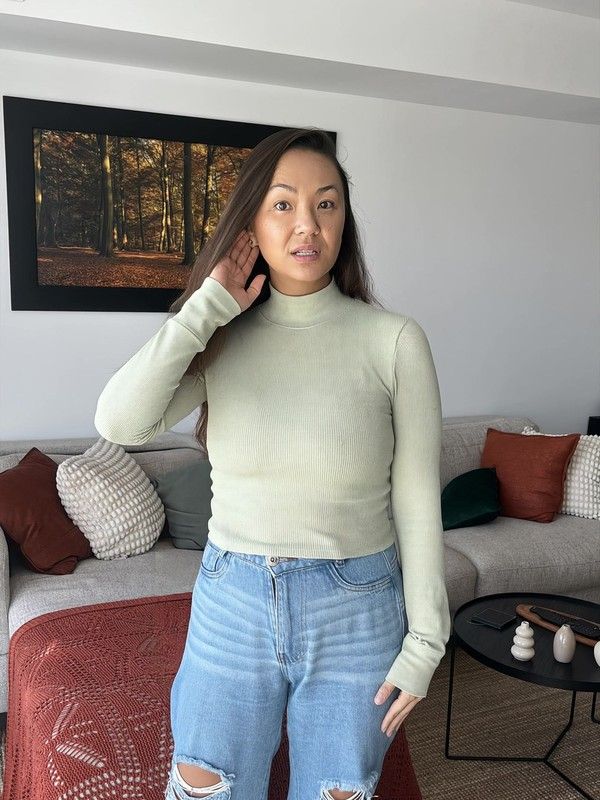
cup an ear
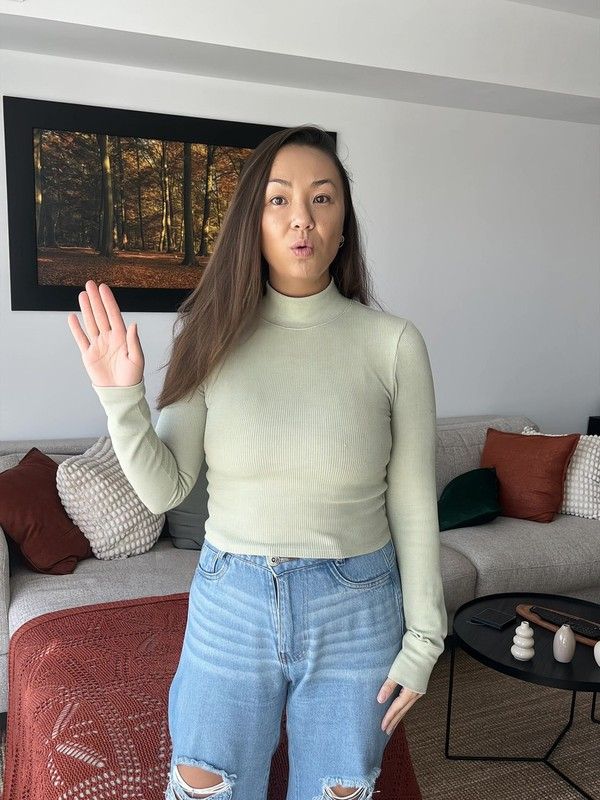
palm to the camera
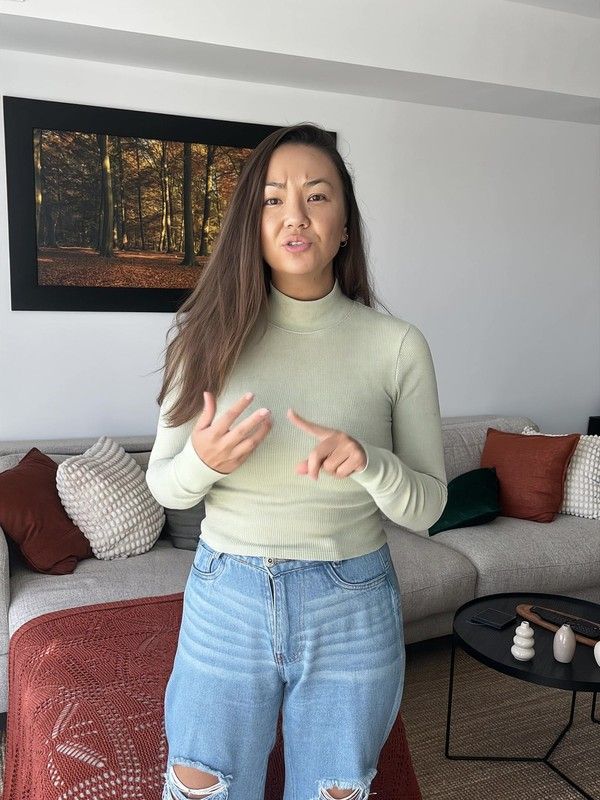
count to three
Prompt Playful storyteller. On ‘not the melody', wag your index finger. On ‘hear it', cup a hand behind your ear. On ‘no, slower', raise a flat palm to the camera. On ‘rain on a window', flutter your fingers downward. On ‘the taste, the choices and the feeling', count to three on your fingers.
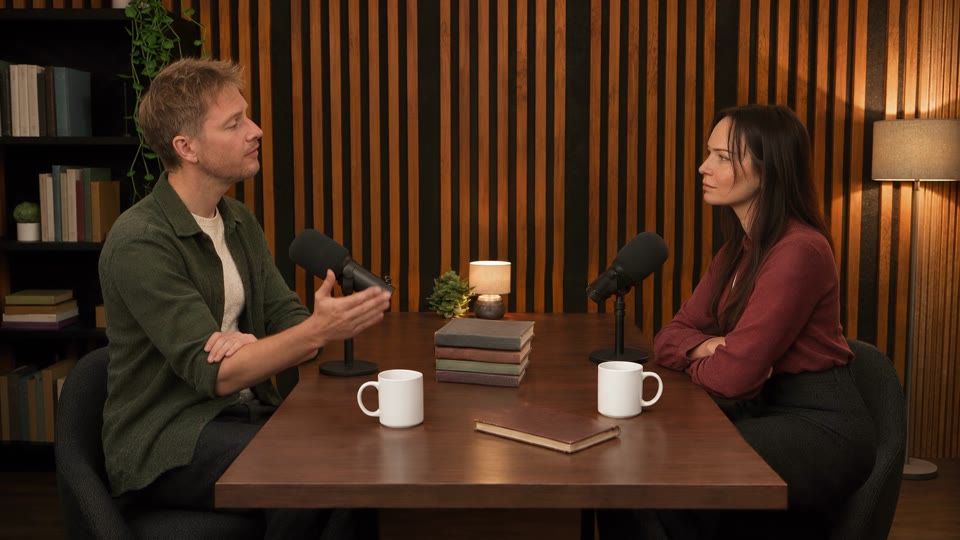
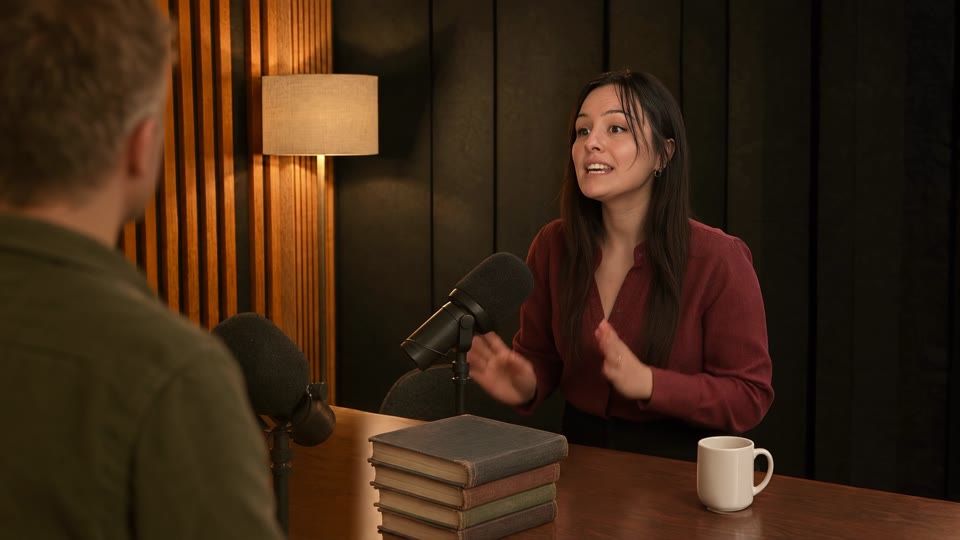
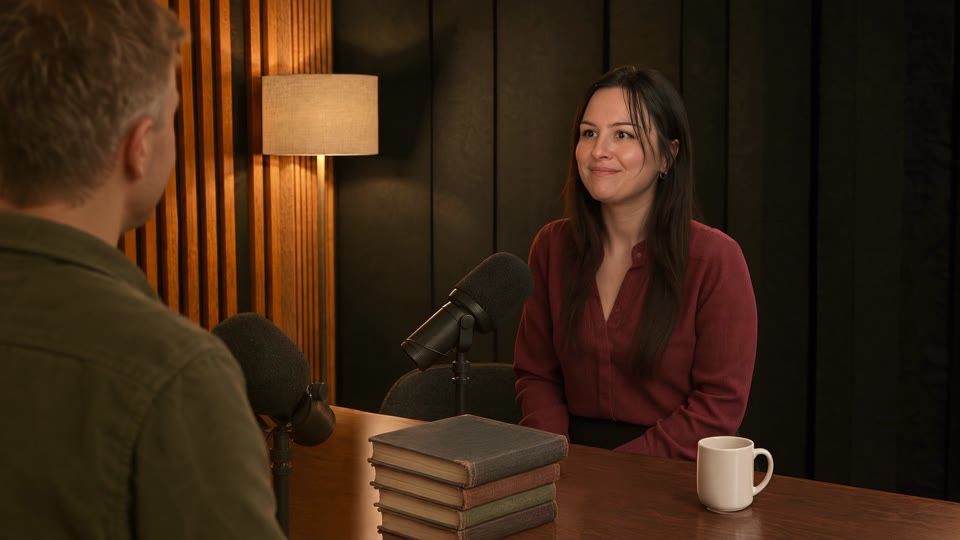
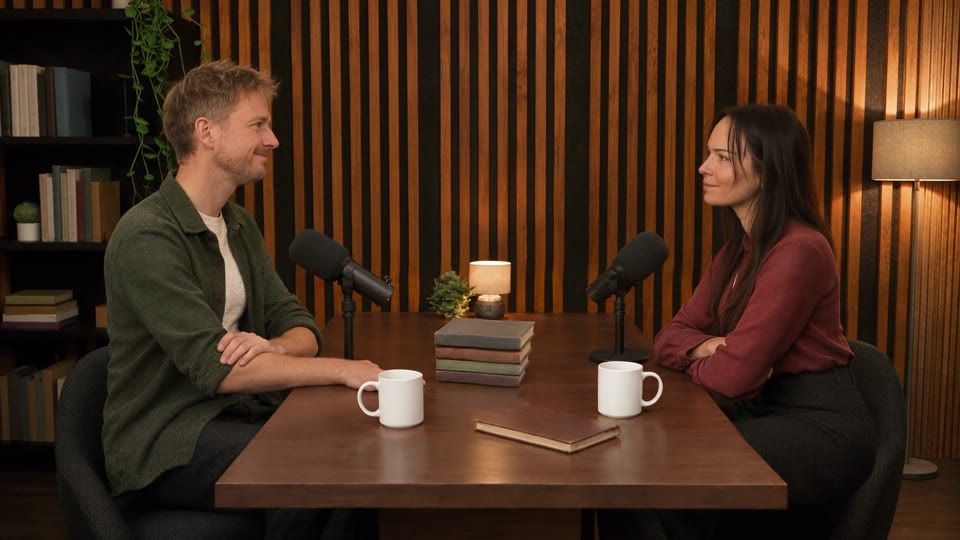
Two speakers, one frame.
A two-minute podcast, host and guest, generated in one go.
Change a word. Keep the recording.
Only the edited words are regenerated, in the person's own voice. Everything else stays as filmed.
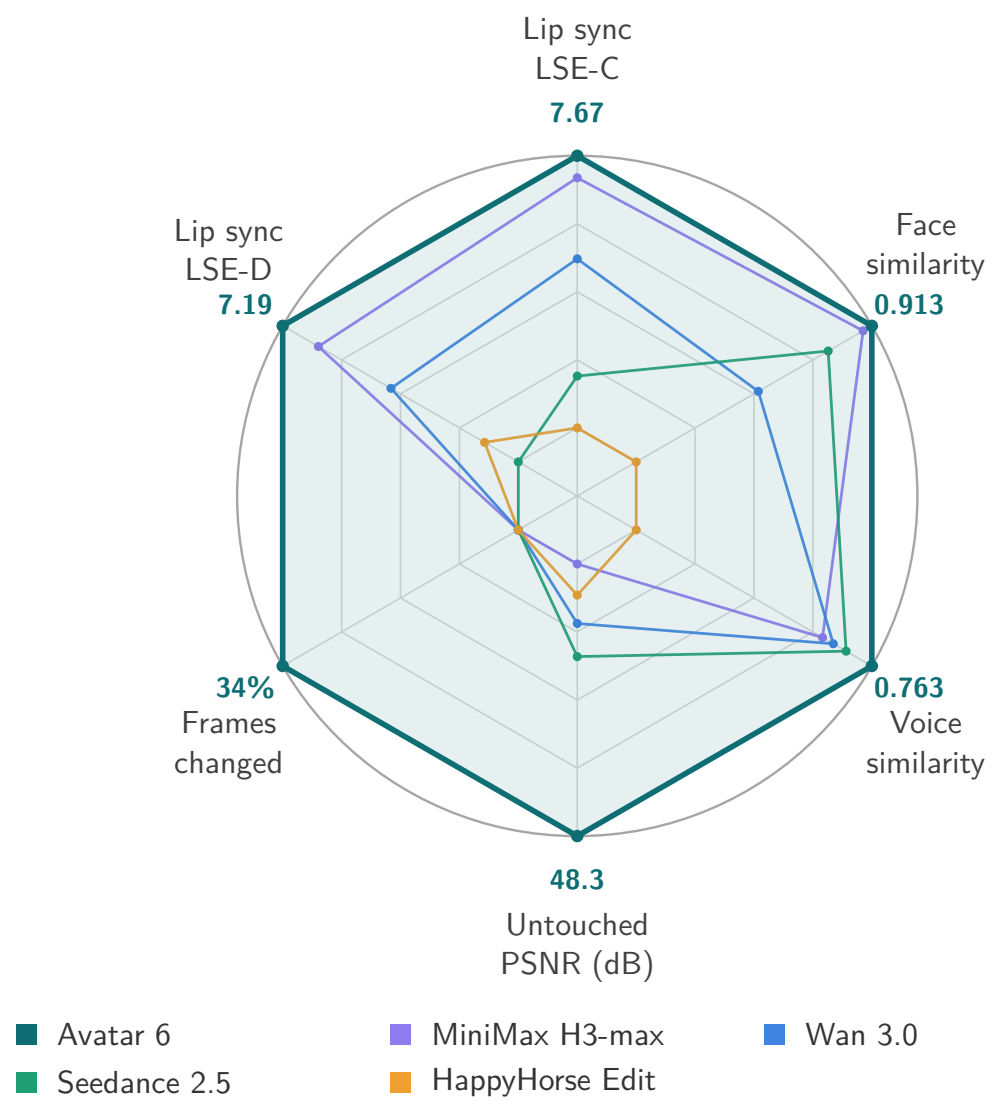
Full table
| Method | Untouched PSNR (dB) ↑ | Frames changed ↓ | Face similarity ↑ | Voice similarity ↑ | Lip sync LSE-C ↑ | Lip sync LSE-D ↓ |
|---|---|---|---|---|---|---|
| MiniMax H3-max | 19.5 | 100.0% | 0.907 | 0.717 | 7.25 | 7.75 |
| Wan 3.0 | 25.8 | 100.0% | 0.835 | 0.727 | 5.70 | 8.89 |
| Seedance 2.5 | 29.3 | 99.7% | 0.883 | 0.739 | 3.46 | 10.89 |
| HappyHorse Edit | 22.8 | 100.0% | 0.751 | 0.543 | 2.47 | 10.36 |
| Avatar 6 | 48.3 | 34.4% | 0.913 | 0.763 | 7.67 | 7.19 |
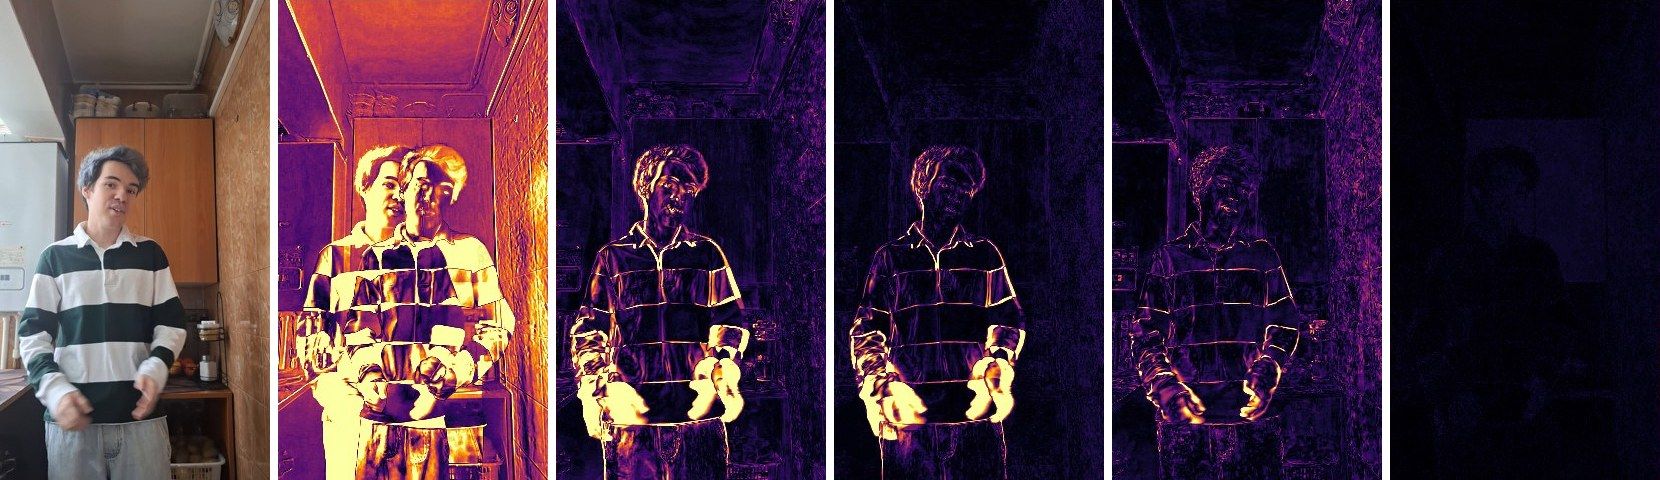
Outside the edit, nothing changes
One frame after the edit, compared with the original: the brighter, the more it changed.
Show the difference images
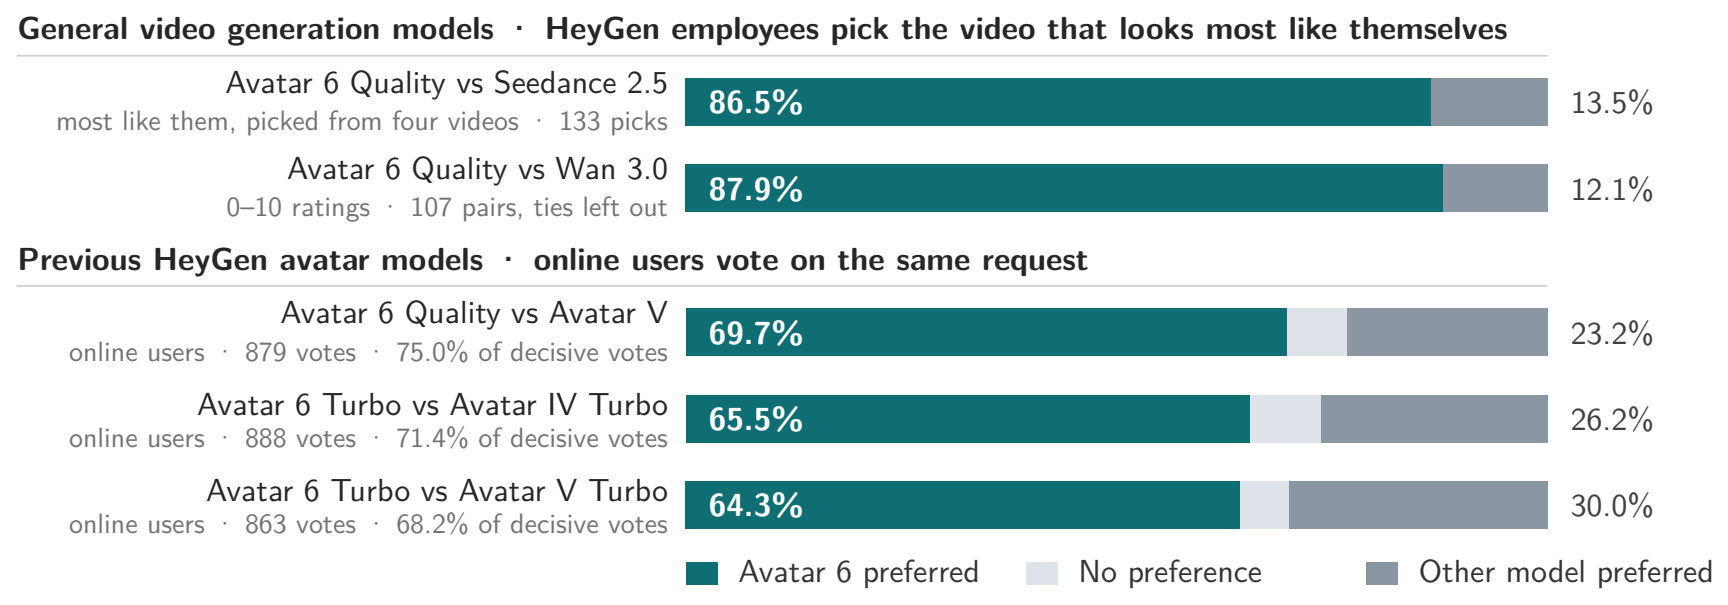
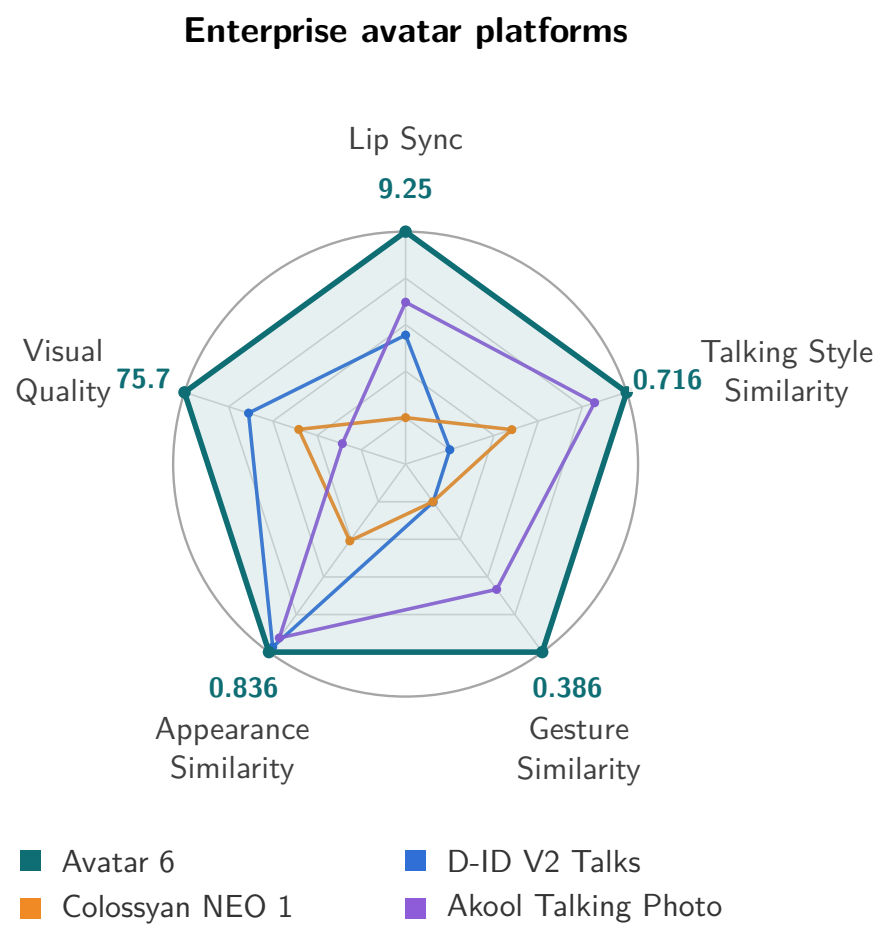
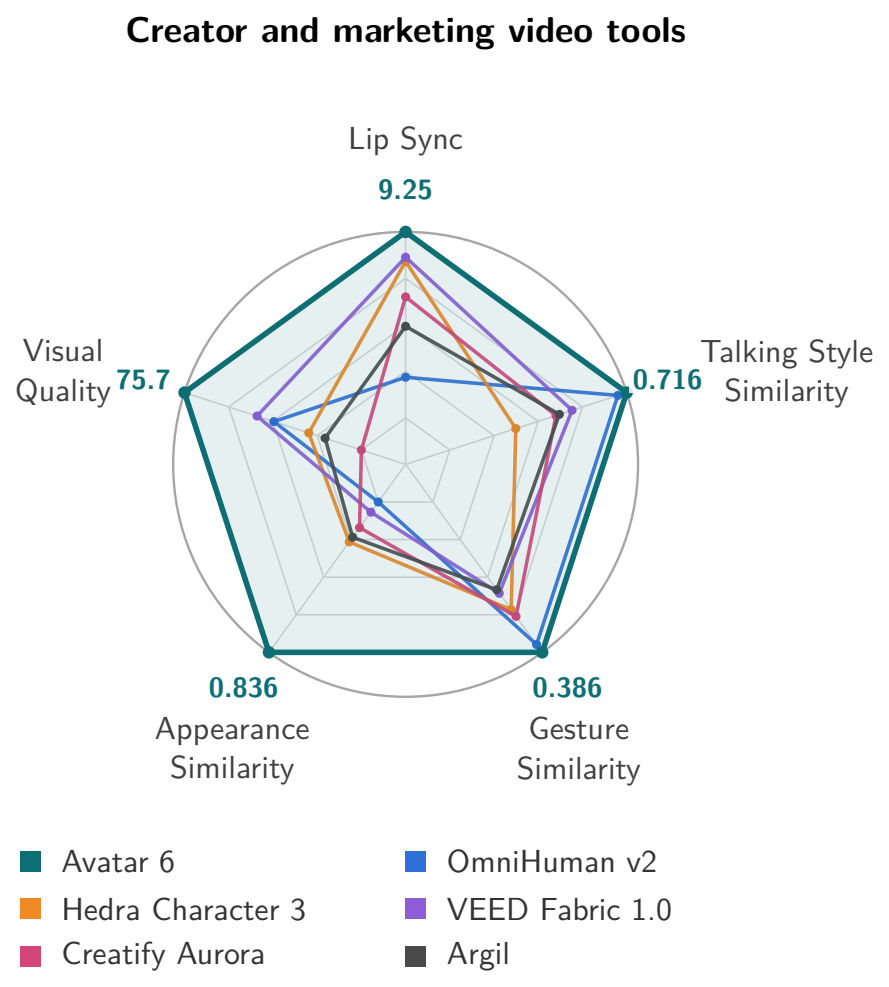
Preferred over the strongest video models.
Against Seedance 2.5, Wan 3.0, our previous models and commercial avatar products. Also first on Avatar Arena.
HeyGen employees compare videos of themselves and pick the one that looks most like them, which only they can tell. Below: online users vote between Avatar 6 and our previous models on the same request.
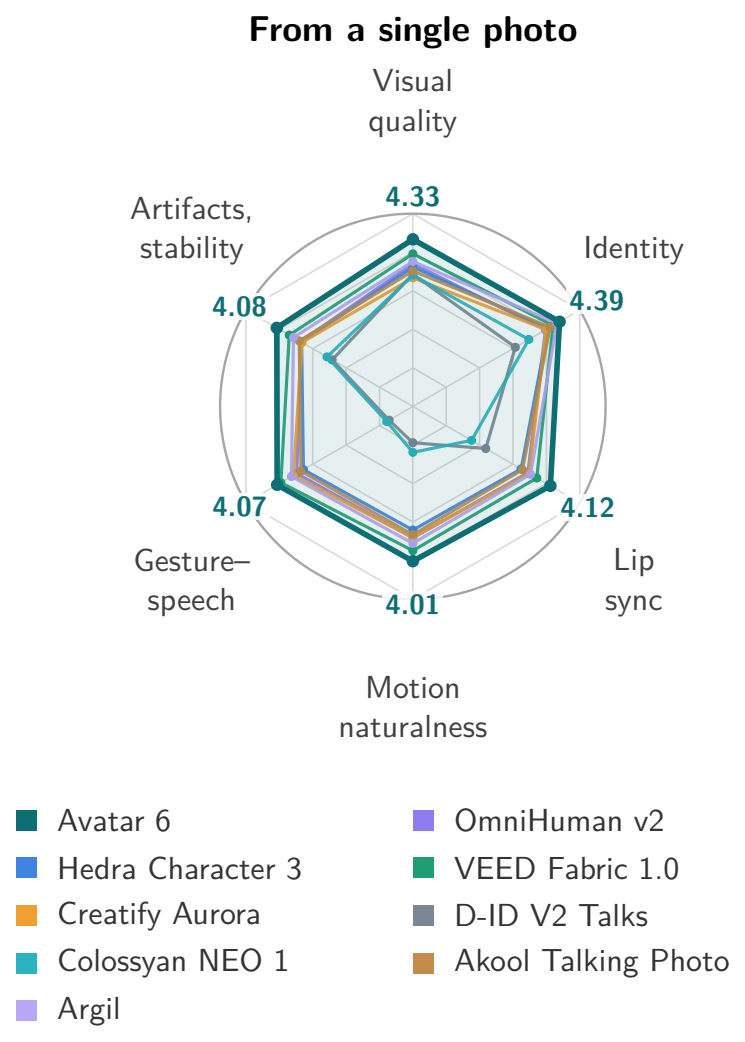
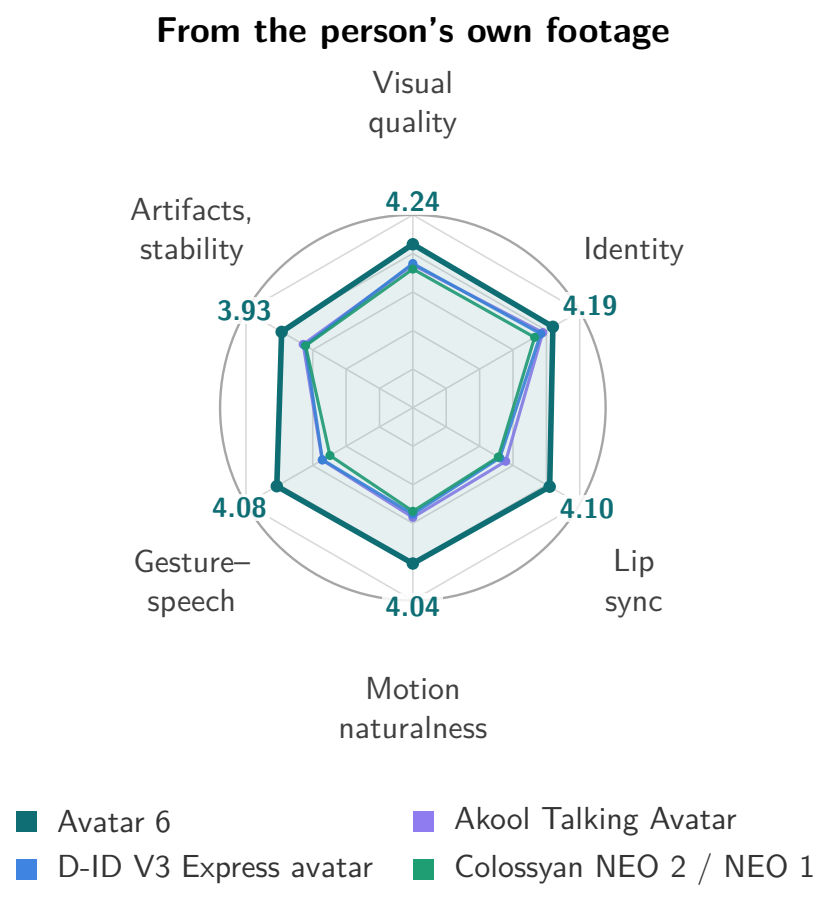
External raters who have never met the person compare two videos for overall quality, lip sync and motion. Without knowing the person, likeness counts for less, so the margin over Seedance 2.5 and Wan 3.0 is smaller than above.
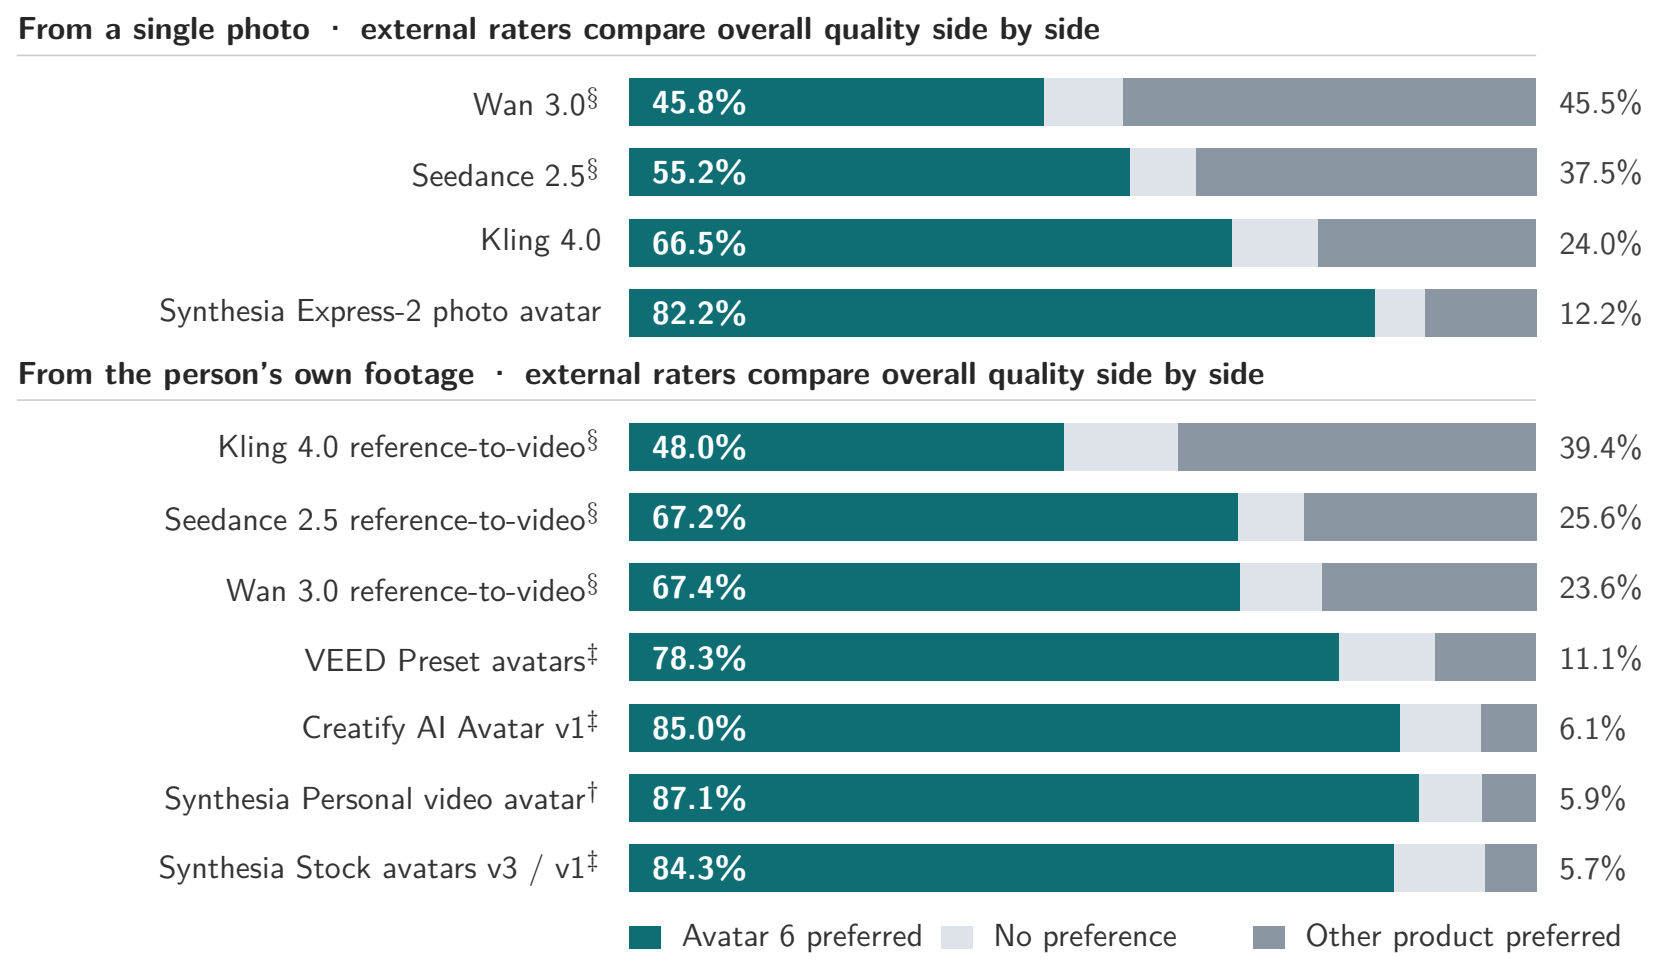
Full rating tables
| Method | Overall | Visual quality | Identity | Lip sync | Motion naturalness | Gesture– speech | Artifacts, stability | Avatar 6 wins |
|---|---|---|---|---|---|---|---|---|
| From a single photo and speech | ||||||||
| VEED Fabric 1.0 | 3.68 | 3.96 | 4.20 | 3.71 | 3.74 | 3.95 | 3.70 | 69.6% |
| OmniHuman v2 | 3.32 | 3.70 | 3.97 | 3.44 | 3.41 | 3.48 | 3.36 | 80.8% |
| Argil image avatar | 3.46 | 3.76 | 4.32 | 3.52 | 3.55 | 3.64 | 3.58 | 80.9% |
| Creatify Aurora | 3.29 | 3.33 | 3.99 | 3.48 | 3.40 | 3.58 | 3.32 | 84.3% |
| Akool Talking Photo | 3.19 | 3.52 | 4.11 | 3.28 | 3.33 | 3.35 | 3.40 | 86.4% |
| Hedra Character 3 | 3.16 | 3.62 | 4.05 | 3.24 | 3.21 | 3.28 | 3.33 | 88.2% |
| D-ID V2 Talks | 1.48 | 3.43 | 3.07 | 2.18 | 0.94 | 0.71 | 2.42 | 97.9% |
| Colossyan NEO 1 Instant avatar | 1.59 | 3.40 | 3.48 | 1.76 | 1.19 | 0.78 | 2.57 | 98.1% |
| Avatar 6 | 4.00 | 4.33 | 4.39 | 4.12 | 4.01 | 4.07 | 4.08 | – |
| From the person's own footage | ||||||||
| Akool Talking Avatar | 2.93 | 3.70 | 3.89 | 2.78 | 2.85 | 2.72 | 3.29 | 92.9% |
| D-ID V3 Express avatar | 2.85 | 3.74 | 3.83 | 2.60 | 2.76 | 2.71 | 3.23 | 95.3% |
| Colossyan NEO 2 / NEO 1 | 2.68 | 3.59 | 3.65 | 2.56 | 2.69 | 2.48 | 3.21 | 97.3% |
| NEO 2, scripts 1–3 | 2.90 | 3.59 | 3.58 | 3.24 | 2.86 | 2.58 | 3.35 | 96.2% |
| NEO 1, scripts 4–5 | 2.35 | 3.60 | 3.74 | 1.55 | 2.43 | 2.34 | 3.01 | 98.9% |
| Avatar 6 | 3.98 | 4.24 | 4.19 | 4.10 | 4.04 | 4.08 | 3.93 | – |
| Avatar 6 vs | Overall | Visual quality | Identity | Lip sync | Motion naturalness | Gesture– speech | Artifacts, stability | Avatar 6 wins |
|---|---|---|---|---|---|---|---|---|
| Photo input | ||||||||
| Wan 3.0§ | −0.01 | +0.55 | +0.09 | +0.01 | −0.18 | −0.19 | +0.04 | 50.1% |
| Seedance 2.5§ | +0.30 | +1.05 | +0.08 | +0.03 | +0.12 | +0.10 | −0.01 | 59.6% |
| Kling 4.0 | +0.79 | +0.66 | +0.14 | +0.42 | +0.69 | +0.81 | +0.30 | 73.5% |
| Synthesia Express-2 photo avatar | +1.50 | +0.96 | +0.55 | +1.21 | +1.56 | +1.51 | +0.58 | 87.0% |
| Footage input | ||||||||
| Kling 4.0 reference-to-video§ | +0.17 | +0.73 | −0.08 | +0.04 | +0.01 | −0.02 | +0.02 | 54.9% |
| Seedance 2.5 reference-to-video§ | +0.61 | +1.10 | +0.40 | +0.14 | +0.18 | +0.21 | +0.03 | 72.4% |
| Wan 3.0 reference-to-video§ | +0.75 | +0.54 | +0.88 | +0.31 | +0.31 | +0.35 | +0.29 | 74.1% |
| VEED Preset avatars‡ | +1.15 | +0.71 | +0.17 | +0.94 | +1.12 | +1.18 | +0.58 | 87.6% |
| Creatify AI Avatar v1‡ | +1.31 | +0.84 | +0.25 | +1.12 | +1.30 | +1.37 | +0.70 | 93.3% |
| Synthesia Personal video avatar† | +1.68 | +1.64 | +0.79 | +1.38 | +1.51 | +1.56 | +1.16 | 93.6% |
| Synthesia Stock avatars v3 / v1‡ | +1.28 | +0.92 | +0.24 | +1.01 | +1.26 | +1.37 | +0.65 | 93.7% |
| v3, four avatars | +1.29 | +0.88 | +0.23 | +1.02 | +1.30 | +1.39 | +0.62 | 92.8% |
| v1, Cooper | +1.26 | +1.05 | +0.28 | +1.00 | +1.12 | +1.27 | +0.75 | 97.5% |
Comparison with Real Footage: Turing Test
Side by side with the real recording, raters pick Avatar 6 as the real one 42.2% of the time. 50% would mean they cannot tell at all, so Avatar 6 is 84.4% of the way there.
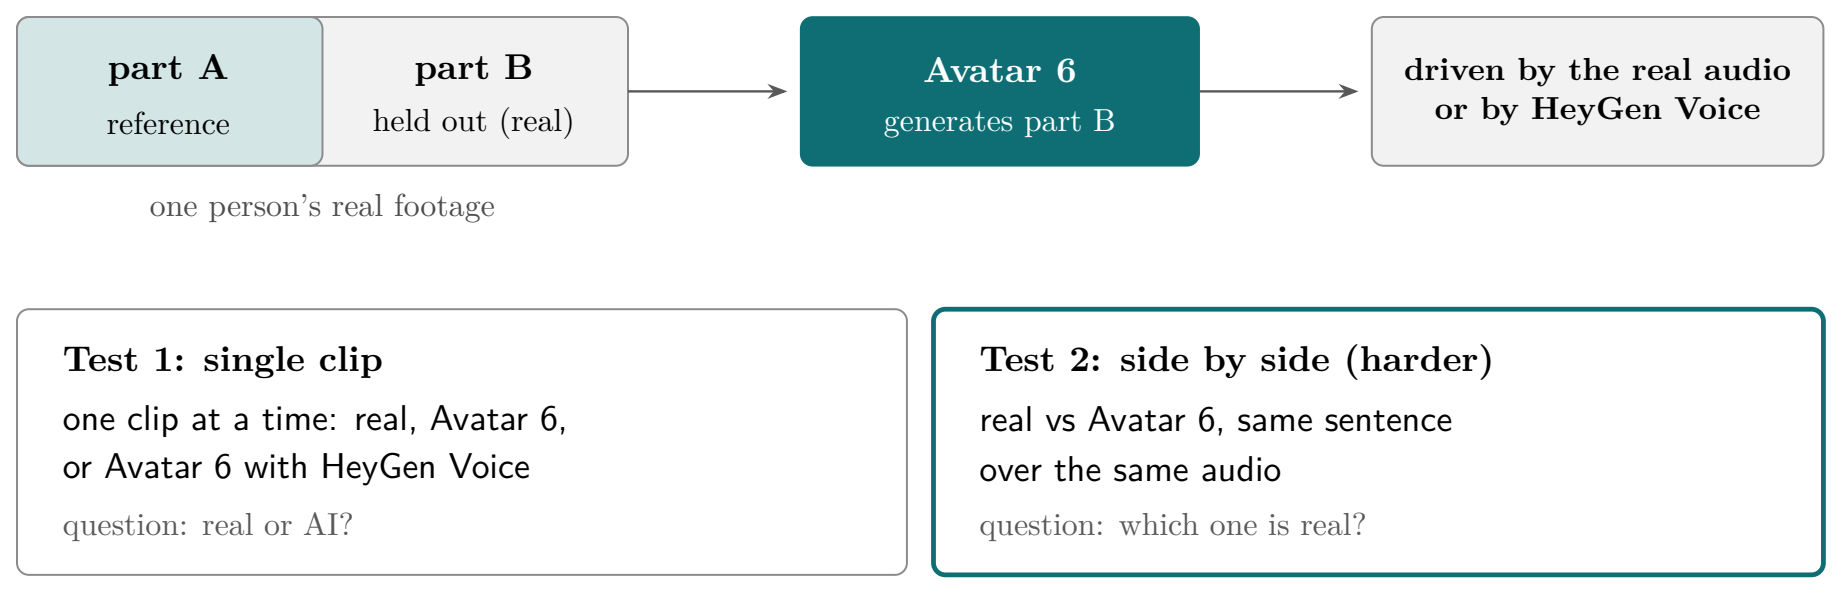
Full results
| Single clip, shown alone | Judged real | Answers |
|---|---|---|
| Real recording | 78.9% | 612 |
| Avatar 6, person's own voice | 65.1% | 304 |
| Avatar 6, HeyGen Voice | 56.5% | 308 |
| Side by side, same sentence and audio | Real picked | Answers |
| Real vs Avatar 6 | 57.8% | 270 |
| Avatar 6 picked as real | 42.2% | 270 |
| Indistinguishability (2× the above) | 84.4% | 270 |
Before an avatar created from a person's footage can generate any video, the person must record a short on-camera consent statement that includes a one-time code generated for that session, so footage recorded in advance or taken from elsewhere cannot satisfy the check; HeyGen then verifies that the person in the consent recording matches the person in the training footage, and the avatar cannot render until this check passes. All people shown in this report are HeyGen employees or contracted actors who consented to the use of their likeness in this report. The AI avatars in Figure 6 are synthetic characters, and the real-person avatars there are HeyGen public stock avatars.