
Before we built a voice model, HeyGen was already a marketplace for voice. Every major engine ran through our product, and every day our users picked between them. That gave us something a voice-only company can't easily get: a live, blind scoreboard with real people judging their own voice. In July, HeyGen Voice entered that scoreboard last. By Sep 28 it was first, and on Oct 9 an independent leaderboard ranked it #1 too.
Weekly blind preference score, from 644,284 picks by real users since late June. A 100-point lead means winning about 64% of one-on-one matchups. ElevenLabs shows its best model each week (v4 from Sep 21). On Aug 17 the test moved into a new clone flow, and every engine gained on ElevenLabs that week.
Our marketplace and our users were the advantage.
We were already one of the biggest places voice gets used.
HeyGen routes speech to ElevenLabs, Cartesia, Fish and others, at roughly 6 billion characters a week before we launched our own model. That meant we already knew where each engine sounded great and where it broke, across real customer videos, languages and voices. We weren't guessing what "good" sounds like. We'd been buying it at scale.
Our users became the largest live voice-clone test we know of.
Voice cloning in HeyGen doubles as a blind test. People hear the same line in their own cloned voice from several engines, play every option, and keep the one that sounds most like them. That adds up to 40,000–63,000 picks a week and 644,284 in total. A paid listening panel gives a few thousand ratings per study. Our raters had every reason to be picky, because it was their own voice.
That gave us a weekly scoreboard against the best in the market.
Every build of HeyGen Voice went into the same test as the engines it had to beat, with the same users and the same sentences, and we saw the result within a week. That's how we knew the Voice 1.0 builds worked: the gap to Cartesia went from 78 points behind to 7 in a single week, and HeyGen has led every week since Sep 28.
And we built the model for what our users actually make: video.
Most cloning models copy everything in your recording, including the phone mic and the room, into every scene. HeyGen Voice keeps who is speaking but takes how and where from the video frame. It's trained on the same talking-video data, GPUs and human-rating program as our Avatar V video model, in five stages ending with tuning on human preference.
Your voiceup to 60 s of you speaking, recorded anywhereThe scenethe frame of the video you're making→HeyGen Voice→You, as you'd sound in that scenesame voice, matched delivery and room
When people clone their voice and hear every engine side by side with no names, they opt for HeyGen Voice more than any other.
Rankings for each phase of the test
Each phase pools every blind pick made in that window. Pick a phase to see where HeyGen Voice stood.
New HeyGen Voice version released · 216,167 picks
Test moves into the footage-clone flow · 207,609 picks
HeyGen Voice enters with pre-1.0 builds · 165,873 picks
Before HeyGen Voice joins the test · 54,635 picks
Preference score on an Elo-style scale, with ElevenLabs v2 fixed at 1000 as the reference. ± is the 95% interval. Scores aren't comparable across the Aug 17 flow change, so compare engines within a phase.
This week's blind matchups, Oct 14–20
Share of all speech generated in HeyGen
HeyGen Voice went from almost none of the speech generated in HeyGen to the largest share, overtaking ElevenLabs in the week of Oct 5.
Weekly share by the engine that ran it. ElevenLabs combines all its models. Includes default and Auto-routed traffic.
What went into building it.
Most voice clones are fine for a sentence or two, then they slip. Over a long script the voice drifts and the room changes. We built HeyGen Voice to hold up over a whole video: every take is anchored to your voice and the scene, so a long script stays in one voice and one room from start to finish. Then we tuned it on the two things people judge their own clone on: does it sound like me, and is every word clear?
- Reward sounding like you, and being understood. Reinforcement learning (GRPO) has the model try several takes of each line, scores every take with speaker verification (is this still your voice?) and speech recognition (is every word clear?), and pushes it toward the takes that score best. This is the released base model.
- Add expression without drifting from your voice. A final round of preference tuning (DPO) trains a small add-on for phrasing, emphasis and rhythm. First an AI judge picks the more expressive of two takes, scoring both against your original recording so a take can't win by sounding less like you. Then human listeners from our Avatar V rating program choose between takes, correcting the cases where the judge and people disagree.
- Let users have the final say. Every build then went into the blind clone test above, judged by people hearing their own voice, before it shipped.
In blind listening tests, listeners rate it clearer than ElevenLabs v4, Cartesia and Inworld.
Read the research: HeyGen Voice: Scene-Aware Voice Cloning for Talking Videos →The full technical report covers the scene-aware architecture, the talking-video training data, all five training stages and every evaluation (PDF).
It isn't only our test that says so.
The strongest check is one we didn't run. On Artificial Analysis's controlled-voice leaderboard, where listeners compare models blind, HeyGen Voice debuted at #1. As of Oct 21, HeyGen Voice Turbo and HeyGen Voice hold the top two spots, ahead of Qwen, ElevenLabs v4 and Cartesia's Sonic 3.6.
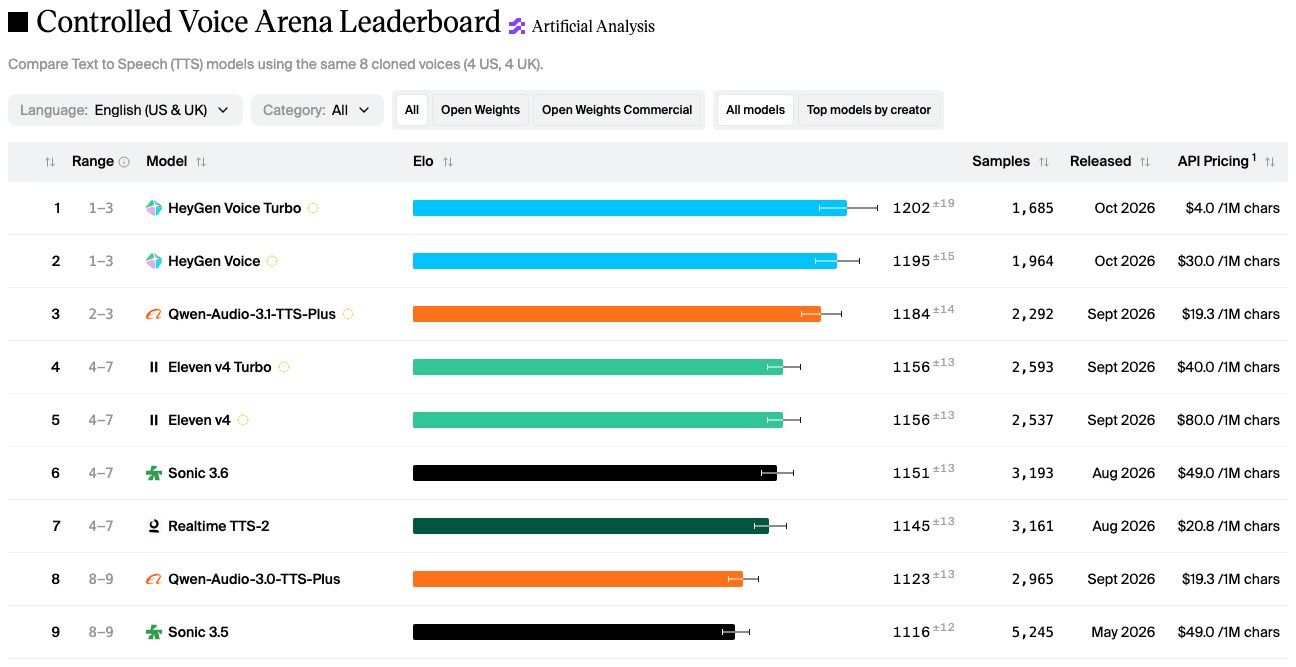
Artificial Analysis Controlled Voice Arena leaderboard, English (US & UK), captured Oct 21, 2026.
Where we're not ahead yet
Against ElevenLabs v4, naturalness is a tie (50.2%), and ElevenLabs leads in Chinese. Its character error rate is also slightly lower (0.013% vs our 0.015%), though at that level it no longer separates models. We publish these because they're the next gaps to close.
We set out to give users a better voice. The savings followed.
Before we moved anyone to HeyGen Voice, it had to beat the best voices on the market blind, judged by the people who'd use it. As users moved over, they rated their voice higher, and we're saving millions a year in costs, which means fewer limits for our users.
Quality went up while costs went down
As users moved to HeyGen Voice, the share of voice ratings that are thumbs-up rose from 73% over the summer to 82.5%, and our ElevenLabs usage cost fell from $11.9M a year to $3.4M.
Thumbs-up rate: weekly share of in-product voice quality ratings that are thumbs-up, US and Tier 1 users (left axis). ElevenLabs usage cost: our weekly usage as metered by ElevenLabs and annualized; lower is better (right axis). Weeks of Jul 6 to Oct 12, 2026.
How the blind test works
Picks. Only explicit, fully informed picks count, meaning the person played every option before choosing. Sets that show the same engine twice are left out.
Scores. Each week, a choice model (Bradley-Terry extended to 2–4 options) is fit to that week's picks and placed on an Elo-style scale with ElevenLabs Multilingual v2 fixed at 1000. When v2 traffic dried up after v4 arrived, the scale was carried across using the v4 − v2 gap (+81). Engines with fewer than 1,000 appearances in a week are left out of that week.
Flow change. On Aug 17 the test moved from the voice-clone modal to the footage-clone flow, and every engine gained on ElevenLabs v2 at once, so compare engines within a week rather than across that date.
Sources. HeyGen clone-flow selection events (Jul 13 – Oct 12, 2026); HeyGen Voice technical report (Oct 10, 2026) for the method, the head-to-head A/B results, the paid listening tests and the Artificial Analysis snapshot.