Ranked first on Artificial Analysis’ voice leaderboard

The #1 voice model.
Built for video

Meet HeyGen Voice, the world’s best voice model and the first built to adapt to video. It delivers your script in your voice, with your pacing and expression, while adapting to the scene’s acoustics.

0:00 / 0:05
HeyGen Voice

The world’s top voice model

All HeyGen Voice needs is a 60-second phone recording to learn your timbre, accent, and phrasing. From there, it looks at the scene and figures out how you’d deliver the line as if you were really standing there.

1. Record your voice

Pavel’s original recording in an everyday room

Original recording

Everyday room

2. HeyGen Voice

HeyGen Voice

  • Keeps your voice
  • Fits each scene
+ Scene image & captions

3. Speech for every scene

Speech for every scene

Built on a new architecture

Add expression without losing your voice

Expressiveness Boost is a separate layer trained on what listeners prefer and scored against your reference the whole way, so it adds emphasis, rhythm, and inflection while staying unmistakably you. It is one slider from your baseline delivery to full energy, and zero gives you the base model back.

Expressiveness Boost · Off

The baseline delivery

Pavel at his desk, baseline delivery
0:00 / 0:21

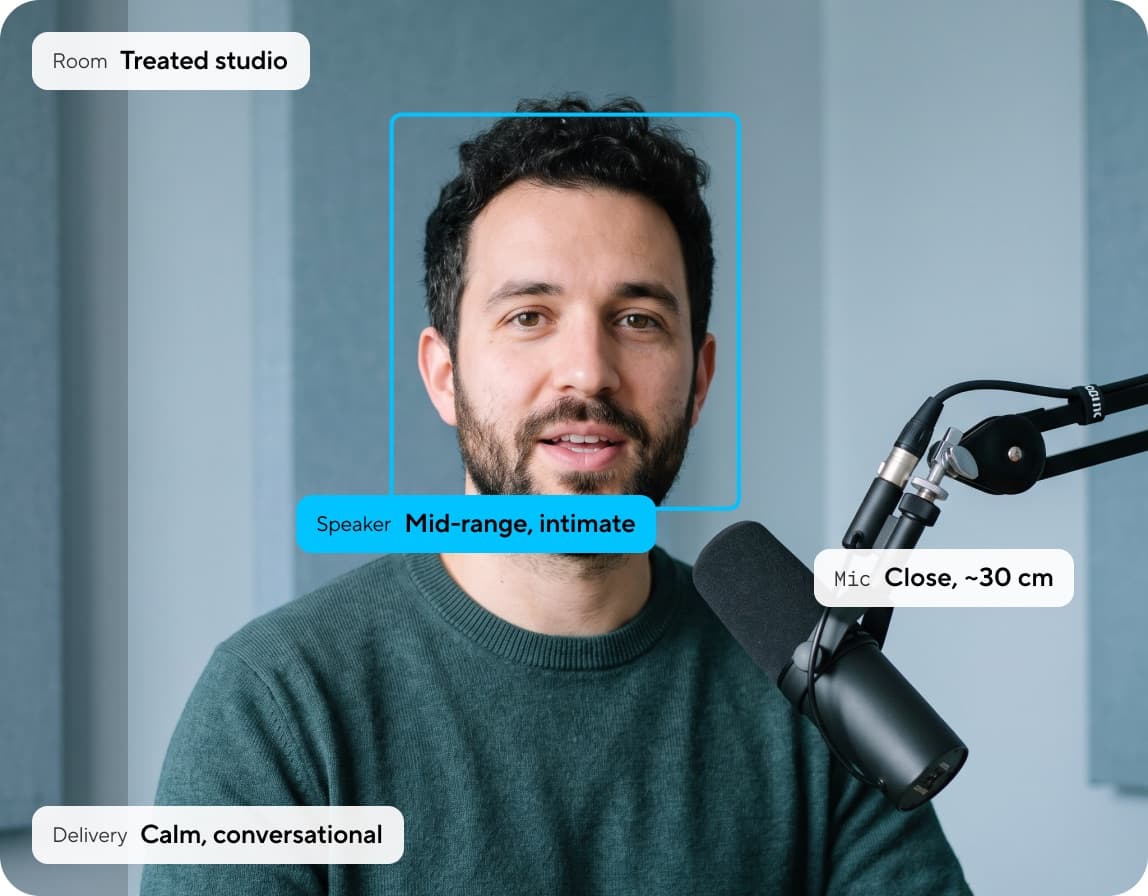
Automatically reads the scene

A vision encoder and two scene captions tell the model the room, the mic distance, and the delivery the picture calls for. Across 50 environments from cathedral to beach, reviewers in our research judged its ambient sound a better fit than ElevenLabs v4, Cartesia Sonic 3.6, or Seedance 2.5.

A speaker at a close microphone in a treated studio, annotated: room, speaker, mic and delivery
Research

Real users pick HeyGen for their own voice

Every voice model says it sounds the most realistic. We’d rather show you the data.

Read the technical report

Evaluation 1: When people hear their own voice, which do they choose?

In the HeyGen app, thousands of people recorded a short voice sample. They heard the same script generated by HeyGen Voice, ElevenLabs v4, and Cartesia Sonic 3.6, unlabeled and in random order, and picked the one to use as their own.

See the data

Chosen as their own voice

Three-way test · 6,153 votes

  • HeyGen Voice41.7%
  • Cartesia Sonic 3.635.3%
  • ElevenLabs v423.0%
0%50%

62.2%

Head-to-head vs ElevenLabs v4 · 8,332 votes

54.1%

Head-to-head vs Cartesia Sonic 3.6 · 7,286 votes

Evaluation 2: Which voice would you want narrating your video?

We also asked testers on Podonos which voices they would choose to narrate an entire lesson across 245 scripts in English, Spanish, German, French, and Chinese, 42,875 ratings in all. They chose HeyGen Voice over ElevenLabs v4 in 61.5% of decided votes, over Inworld TTS-2 in 68.1%, and over Cartesia Sonic 3.6 in 77.9%. It also led every system in clarity and native accent.

See the data

Chosen to narrate a full lesson

HeyGen Voice’s share of decided votes

  • vs Cartesia Sonic 3.677.9%+27.9
  • vs Inworld TTS-268.1%+18.1
  • vs ElevenLabs v461.5%+11.5

Share of decided narrator-choice votes, 245 cases, five languages, Holm-corrected p < 0.05.

Evaluation 3: Does it sound like it was recorded there?

A voice can sound exactly like you and still sound wrong for the shot. So we put the same voice in 50 places, including a podcast booth, cathedral, beach, and factory floor. We asked reviewers one blind question: does the sound match the picture? It did. Reviewers chose HeyGen Voice over Cartesia Sonic 3.6 in 73.3% of votes, over ElevenLabs v4 in 69.7%, and over Seedance 2.5 in 65.3%.

See the data

Sound matches the picture

HeyGen Voice’s share of decided votes on ambient fit

  • vs Cartesia Sonic 3.673.3%+23.3
  • vs ElevenLabs v469.7%+19.7
  • vs Seedance 2.565.3%+15.3

Share of decided votes on ambient sound fit, 50 scenes × 5 reviewers, blind side-by-side video, Holm-corrected p < 0.05.

A voice by the ocean

Listen to how the voice fits an open shoreline, with the sea stretching out behind the speaker.

HeyGen VoiceSees the scene
HeyGen Voice speaking on a beach
ElevenLabs v4
ElevenLabs v4 speaking on a beach

Same script and reference voice within each scene. HeyGen Voice also receives the scene image.

Exact Mode

Optimized to sound exactly like you

HeyGen Voice wins 63% of voice-similarity votes against ElevenLabs v4 and ties Cartesia Sonic 3.6 at the top of the similarity scale.

Choose the mode you need

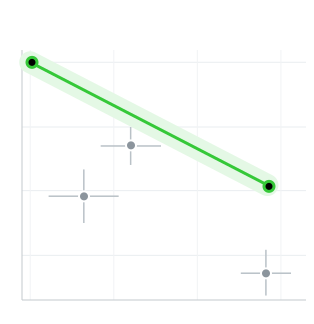
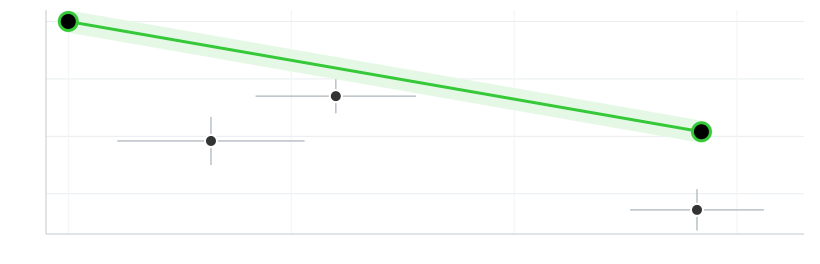
Voice Clone fits delivery and adapt to the script, and Full Clone preserves the session you recorded. The two cover ranges that each competing model occupies at a single point.

↑ Chosen as narratorMore like your recording →
Voice CloneAdaptive to scene
Full CloneExactly like you
ElevenLabs v4Inworld TTS-2Cartesia Sonic 3.6
↑ Chosen as narratorMore like your recording →
Voice CloneAdaptive to scene
Full CloneExactly like you
ElevenLabs v4Inworld TTS-2Cartesia Sonic 3.6

HeyGen Voice: Two modes

Other models: One point each
Scene Mode leads on narrator choice. Exact Mode leads on sounding like your recording. Other models sit at a single point.

Create your HeyGen Voice

Keep your voice across languages

The same recording reads Spanish, German, French, or Chinese with a native accent. In cross-language cases, listeners chose HeyGen Voice as narrator over Cartesia Sonic 3.6 in 77.4% of decided votes.

SOURCEEnglish→ESEspañolDEDeutschFRFrançaisZH中文KO한국어+

Set the similarity level

Similarity parameter is a scale between "Adapts to scene" and "Sounds exactly like you". In the product it's a scale from 1 to 4 for you to customize.

Similarity14
Create your voice

Start from a recording

1

Capture your voice

Upload up to 60 seconds of audio from any device and HeyGen Voice keeps the person and drops the phone.

2

Go further with the Professional Voice model

Give HeyGen Voice 30 minutes to two hours of your recordings, and it learns the finer details, like how your accent moves across words.

ReferenceOriginal recordingAdam’s own voice · what both clones learn from
Instant30 secReady in minutes
Professional30 min–2 hrTrained to your full range

Set the scene

Pitch variation, background level, and ambient steadiness are each a slider, so the same scene can play nearly clean or clearly busy.

  • Pitch variation44
  • Background level73
  • Ambient steadiness85
Pricing

Free in the app. Pay per character on the API

HeyGen App

Free

HeyGen Voice is included in every HeyGen video at no extra cost.

Get started

HeyGen PVC

$29/mo$99/mo

The Professional Voice Clone add-on trains on up to two hours of your voice so that every inflection, pause, and quirk comes with you.

Get started

API

$30per 1M characters

No packages, no minimums, no tiers. Pay for what you generate.

View docs
API

Bring HeyGen Voice to your app via API

Generate speech from your professional voice clone with one REST request, or stream audio as it’s generated.

Access the HeyGen Voice API

REST and streaming endpoints with SDKs for [Python, Node, and others].

  • Set a seed to keep delivery consistent across renders
  • Send a voice ID, text, and language. Get back a WAV file URL and its duration
  • Stream audio parts over SSE as they’re generated, with optional word timestamps you can use to build captions
View docs
generate.py
import osimport requestsresponse = requests.post(    "https://api.heygen.com/v3/models/audio/tts",    headers={"X-Api-Key": os.environ["HEYGEN_API_KEY"]},    json={        "voice_id": "your_professional_voice_id",        "text": "Welcome back. Today we're recording from the studio.",        "language": "en",        "seed": 7,    },)response.raise_for_status()audio_url = response.json()["data"]["audio_url"]with open("studio.wav", "wb") as f:    f.write(requests.get(audio_url).content)

The #1 voice model. Built for video

Meet HeyGen Voice, the world’s best voice model and the first built to adapt to video.

CTA background